



Navigating the Generative AI Risk Landscape: Insights from MIT CISR
-
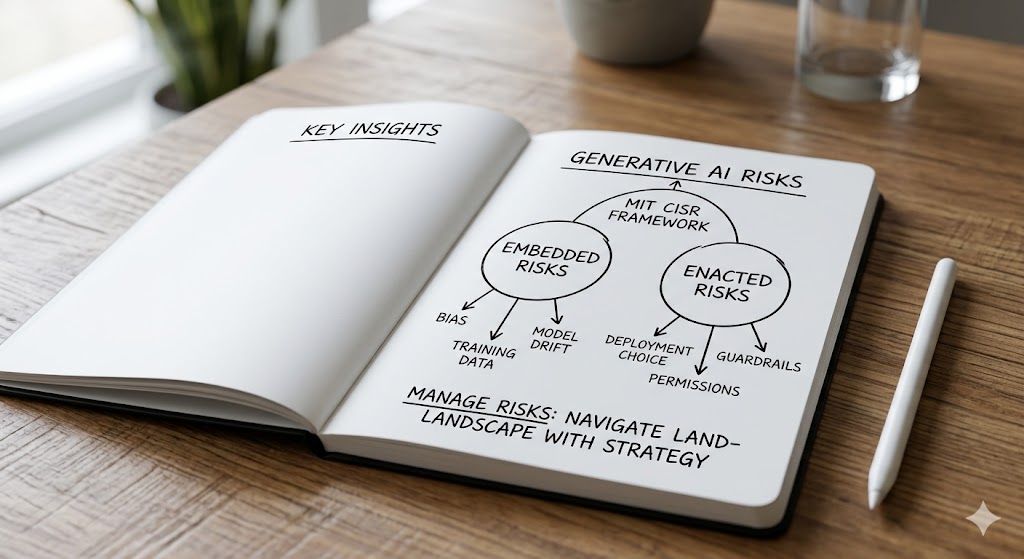
Classification of Risks: The framework distinguishes between embedded risks, which are inherent to the foundation models and training data (such as bias and model drift), and enacted risks, which arise from how an organization chooses to deploy and configure the AI (such as prompt engineering and user permissions).
-
Expansion of the Risk Surface: As organizations move toward more advanced implementations like Retrieval-Augmented Generation (RAG) and autonomous AI agents, new vulnerabilities emerge, including data quality issues in vector databases and “autonomy creep” where agents might perform unauthorized tasks.
-
Strategic Action Plan: MIT CISR recommends a proactive approach involving mapping exposure by inventorying all GenAI tools, differentiating management styles based on the risk type, and establishing clear ownership with comprehensive audit trails for prompts and outputs.
Generative AI (GenAI) offers staggering potential for innovation and productivity, yet it simultaneously introduces a new frontier of complex business risks. Moving from experimental phases to full-scale deployment requires a sophisticated understanding of these risks and intentional management strategies. Recent research from the MIT Center for Information Systems Research (CISR), drawing on interviews with 62 data and technology executives, provides a valuable framework for understanding and mitigating these emerging threats.
MIT CISR researchers Nick van der Meulen, Hippolyte Lefebvre, and Barbara Wixom categorize GenAI risks into two fundamental types: embedded and enacted. This distinction is critical because each type requires a different management approach.
Embedded risks are inherent to the technology itself. They are built into the foundation models an organization adopts and are shaped by the quality of the training data, model behavior, and performance drift. These risks, such as biases present in the training data or opaque model reasoning, are not fully within an organization’s direct control but must be carefully assessed and monitored.
Enacted risks, conversely, stem from the choices organizations make regarding how they deploy, configure, and use generative AI. These encompass the design of system prompts, the implementation of safeguards against attacks, and the permissions granted to autonomous AI agents. Organizations have greater control over enacted risks, but they require diligent governance and strategic oversight.
The research highlights several key areas, illustrated through the example of an HR manager using AI to draft job descriptions, where risks are most likely to emerge:
-
Training Data: Foundation models are trained on massive datasets that can inherit societal biases, outdated information, or inaccurate data. This can lead to biased outputs, like job descriptions reflecting outdated HR norms or industry practices.
-
Foundation Models: Large language models (LLMs) can exhibit inconsistent behavior, generating different responses to identical inputs and producing “hallucinations”—plausible-sounding but factually incorrect content. The lack of transparency in these models makes error diagnosis challenging.
-
User Prompts: An LLM’s response quality depends heavily on the input prompt. Poorly constructed prompts yield poor results. More critically, users may inadvertently include confidential data, proprietary information, or personally identifiable information (PII) in their prompts, creating significant data privacy risks.
-
System Prompts: These “hidden” instructions enforce organizational context and safety guardrails. Poorly engineered system prompts can create widespread vulnerabilities, while overly rigid ones can stifle creativity and effectiveness.
As organizations advance to more sophisticated deployments, the risk space expands further. Retrieval-Augmented Generation (RAG), which integrates LLMs with proprietary internal data, can surface data quality issues or expose sensitive information that was previously hard to find due to control gaps in vector databases. Furthermore, AI Agents that can act autonomously introduce risks of reduced visibility, difficulty in tracking data flow, and “autonomy creep,” where agents perform unauthorized tasks without sufficient oversight.
To successfully navigate this landscape, MIT CISR recommends a three-part action plan:
-
Map Exposure: Inventory all generative AI tools and solutions in use. Document the underlying foundation models, system prompt design, connected data assets, and human review processes. Establish clear accountability and permission structures.
-
Differentiate Management: Adopt distinct approaches for managing embedded and enacted risks. Embedded risks require engaging with vendors for evaluation, contractual transparency, and change notifications. Enacted risks mandate a robust framework of internal governance capabilities and technical controls.
-
Assign Ownership: Establish clear ownership of ongoing risk assessments and create comprehensive audit trails that log prompts, outputs, and human interventions. Given the high stakes, understanding and mitigating GenAI risks is not just a technical challenge but a strategic imperative.